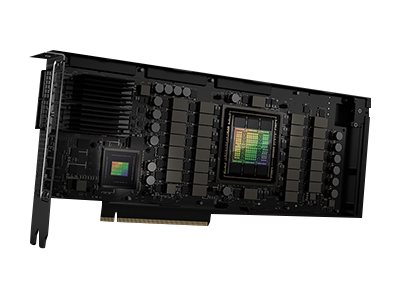
NVIDIA H100 - GPU computing processor
 NOTE: The information below is provided for your convenience only; the accuracy of the specifications cannot be guaranteed. However, if necessary, please check with us before purchasing. Data provided by 1 World Sync.
Technical data
General
Device Type
GPU computing processor
Bus Type
PCI Express 5.0 x32
Graphics Engine
NVIDIA H100 Tensor Core
Features
NVIDIA NVLink technology
Memory
Size
80 GB
Technology
HBM2E
Bandwidth
2000 GBps
Miscellaneous
Power Consumption Operational
350 Watt
Compatibility Information
Designed For
NVIDIA DGX H100
NVIDIA H100 - GPU computing processor - NVIDIA H100 Tensor Core - 80 GB HBM2E - PCIe 5.0 x32 - for NVIDIA DGX H100
Tap into unprecedented performance, scalability, and security for every workload with the NVIDIA H100 Tensor Core GPU. The GPU also includes a dedicated transformer engine to solve trillion-parameter language models. The H100's combined technology innovations can speed up large language models (LLMs) by an incredible 30x over the previous generation to deliver industry-leading conversational AI.
- Transformational AI training
- Real-time deep learning inference
- Exascale high-performance computing
- Accelerated data analytics
- Enterprise-ready utilization
- Transformational AI training
H100 features fourth-generation Tensor Cores and a Transformer Engine with FP8 precision that provides up to 9X faster training over the prior generation for mixture-of-experts (MoE) models. The combination of fourth-generation NVLink, which offers 900 Gigabytes per second (GB/s) of GPU-to-GPU interconnect; NVLink Switch System, which accelerates communication by every GPU across nodes; PCIe Gen5; and NVIDIA Magnum IO software delivers efficient scalability from small enterprise systems to massive, unified GPU clusters. Deploying H100 GPUs at data center scale delivers outstanding performance and brings the next generation of exascale high-performance computing (HPC) and trillion-parameter AI within the reach of all researchers. - Real-time deep learning inference
AI solves a wide array of business challenges, using an equally wide array of neural networks. A great AI inference accelerator has to not only deliver the highest performance but also the versatility to accelerate these networks. H100 extends NVIDIA's market-leading inference leadership with several advancements that accelerate inference by up to 30X and deliver the lowest latency. Fourth-generation Tensor Cores speed up all precisions, including FP64, TF32, FP32, FP16, INT8, and now FP8, to reduce memory usage and increase performance while still maintaining accuracy for LLMs. - Exascale high-performance computing
The NVIDIA data center platform consistently delivers performance gains beyond Moore's law. And H100's breakthrough AI capabilities further amplify the power of HPC + AI to accelerate time to discovery for scientists and researchers working on solving the world's most important challenges. H100 triples the floating-point operations per second (FLOPS) of double-precision Tensor Cores, delivering 60 teraflops of FP64 computing for HPC. AI-fused HPC applications can also leverage H100's TF32 precision to achieve one petaflop of throughput for single-precision matrix-multiply operations, with zero code changes. H100 also features DPX instructions that deliver 7x higher performance over A100 and 40x speedups over CPUs on dynamic programming algorithms such as Smith-Waterman for DNA sequence alignment and protein alignment for protein structure prediction. - Accelerated data analytics
Data analytics often consumes the majority of time in AI application development. Since large datasets are scattered across multiple servers, scale-out solutions with commodity CPU-only servers get bogged down by a lack of scalable computing performance. Accelerated servers with H100 deliver the compute power - along with 3 Terabytes per second (TB/s) of memory bandwidth per GPU and scalability with NVLink and NVSwitch - to tackle data analytics with high performance and scale to support massive datasets. Combined with NVIDIA Quantum-2 InfiniBand, Magnum IO software, GPU-accelerated Spark 3.0, and NVIDIA RAPIDS, the NVIDIA data center platform is uniquely able to accelerate these huge workloads with unparalleled levels of performance and efficiency. - Enterprise-ready utilization
IT managers seek to maximize utilization (both peak and average) of compute resources in the data center. They often employ dynamic reconfiguration of compute to right-size resources for the workloads in use. Second-generation Multi-Instance GPU (MIG) technology in H100 maximizes the utilization of each GPU by securely partitioning it into as many as seven separate instances. With confidential computing support, H100 allows secure, end-to-end, multi-tenant usage, making it ideal for cloud service provider (CSP) environments. H100 with MIG lets infrastructure managers standardize their GPU-accelerated infrastructure while having the flexibility to provision GPU resources with greater granularity to securely provide developers the right amount of accelerated compute and optimize usage of all their GPU resources.
Inside NetworkDistri
From our network to yours.
Every day, technology moves through our operation — received, checked, prepared and dispatched to customers. The images below show real equipment handled through our operation, not stock photography.